APIs should return HTTP 429 when a client sends too many requests, and they should pair it with clear retry guidance so traffic slows down instead of turning into a failure storm. A 429 response is not just an error. It is a traffic signal. Good systems use it to protect uptime, control cost, and keep fair access across users.
TLDR: HTTP 429 means “slow down please,” while Retry-After tells the client how long to wait before trying again. For example, if a billing API allows 100 requests per minute and one client sends 160, the server may return 429 with Retry-After: 30. In one common SaaS pattern, smart retry logic can cut failed repeat calls by 40% to 70% during traffic spikes. The best setup combines rate limits, backoff, queues, monitoring, and clear developer docs.
What HTTP 429 Really Means
HTTP 429 Too Many Requests is the standard response when a client exceeds a rate limit. It tells the client that the server understood the request but will not process it right now because too many similar requests have arrived in a short period.
This protects the API from overload. It also protects other users from one noisy client. Without 429, an API may slow down for everyone, return random 500 errors, or collapse under retry traffic. That is the ugly part. Bad retry behavior can turn a small spike into a full outage.
A typical 429 response looks like this:
HTTP/1.1 429 Too Many Requests
Content-Type: application/json
Retry-After: 60

{
  "error": "rate_limit_exceeded",
  "message": "Too many requests. Try again later."
}
The status code says what happened. The response body explains it. The Retry-After header tells the client when it may try again.
Rate Limiting vs Retry-After
Rate limiting is the rule. Retry-After is the instruction after the rule has been hit.
- Rate limit: Defines how many requests are allowed in a time window.
- HTTP 429: Signals that the client crossed that limit.
- Retry-After: Tells the client how long to wait before sending another request.
For example, an API may allow 1,000 requests per hour per API key. If a client sends 1,001 requests inside that hour, the API can reject the extra request with 429. If the reset happens in 12 minutes, the server may send Retry-After: 720.
Retry-After can be sent in two common formats:
- Seconds:
Retry-After: 30 - HTTP date:
Retry-After: Wed, 21 Oct 2026 07:28:00 GMT
Seconds are simple and common for APIs. Dates are useful when the server wants to point to a fixed reset time.
Why 429 Is Better Than Silent Failure
Some systems still fail badly under traffic pressure. They time out. They return vague 503 errors. They make clients guess. Honestly, it feels like the API just shrugs and leaves the developer to clean up the mess.
A clear 429 response is better. It gives the client a known cause. It also gives the server room to recover. When clients obey retry timing, traffic becomes smoother. Instead of thousands of instant repeat attempts, requests spread out over seconds or minutes.
This matters for checkout systems, login flows, search APIs, ad platforms, payment gateways, and AI APIs. A 429 during a batch import is annoying. A 429 during payment confirmation can create support tickets, duplicate attempts, and angry users.
Common Rate Limiting Strategies
API teams usually pick one or more rate limiting models. Each has tradeoffs.
- Fixed window: Allows a set number of requests per time block, such as 500 per minute. It is easy to understand but can allow bursts at window edges.
- Sliding window: Tracks usage over a rolling period. It is fairer but costs more to compute.
- Token bucket: Gives clients tokens over time. Each request spends a token. It allows short bursts without losing control.
- Leaky bucket: Processes requests at a steady rate. Extra traffic waits or gets rejected.
- Concurrent limit: Caps active requests at the same time, such as 20 open requests per account.
Many production APIs combine these. A client may have a per-second burst limit, a per-hour quota, and a maximum number of active requests. That sounds strict, but it prevents one integration from eating the whole service.
How Clients Should Handle 429
Client applications should not hammer the API after a 429. That is the fastest way to make things worse. They should pause, respect Retry-After, and retry with care.
A good client pattern includes:
- Read the Retry-After header. If it exists, follow it.
- Use exponential backoff. Wait longer after each failed retry.
- Add jitter. Randomize wait times slightly so all clients do not retry at once.
- Set a retry limit. Endless retries waste resources and hide bugs.
- Log rate limit events. Teams need proof when traffic patterns break limits.
For example, a client may wait 2 seconds, then 4, then 8, with a small random delay added each time. If the server sends Retry-After: 45, the client should wait 45 seconds instead. Server guidance should win.
How API Providers Should Design 429 Responses
A bare 429 with no details is technically valid, but it is not helpful. It drives teams crazy when a request fails and the response gives no reset time, no limit name, and no clue which quota was hit. That can add 20 minutes to debugging for no good reason.
Strong 429 responses should include useful headers such as:
Retry-After: How long to wait before retrying.X-RateLimit-Limit: The total allowed requests in the window.X-RateLimit-Remaining: Requests left in the current window.X-RateLimit-Reset: Time when the limit resets.
Some APIs use the newer RateLimit-Limit, RateLimit-Remaining, and RateLimit-Reset headers. Either style can work if it is documented and consistent.
The response body should be readable too:
{
  "error": "rate_limit_exceeded",
  "limit": "100 requests per minute",
  "retry_after_seconds": 30,
  "request_id": "req_7f92"
}
The request_id helps support teams trace the event. That one small field can save hours during incident review.
Traffic Management Beyond 429
429 is only one part of API traffic management. Mature systems also use queues, caching, quotas, priority rules, and circuit breakers.
Queues help when work can be delayed, such as report generation or bulk imports. Caching cuts repeated reads. Priority tiers allow paid or critical traffic to continue during spikes. Circuit breakers stop repeated calls to a failing service before the failure spreads.
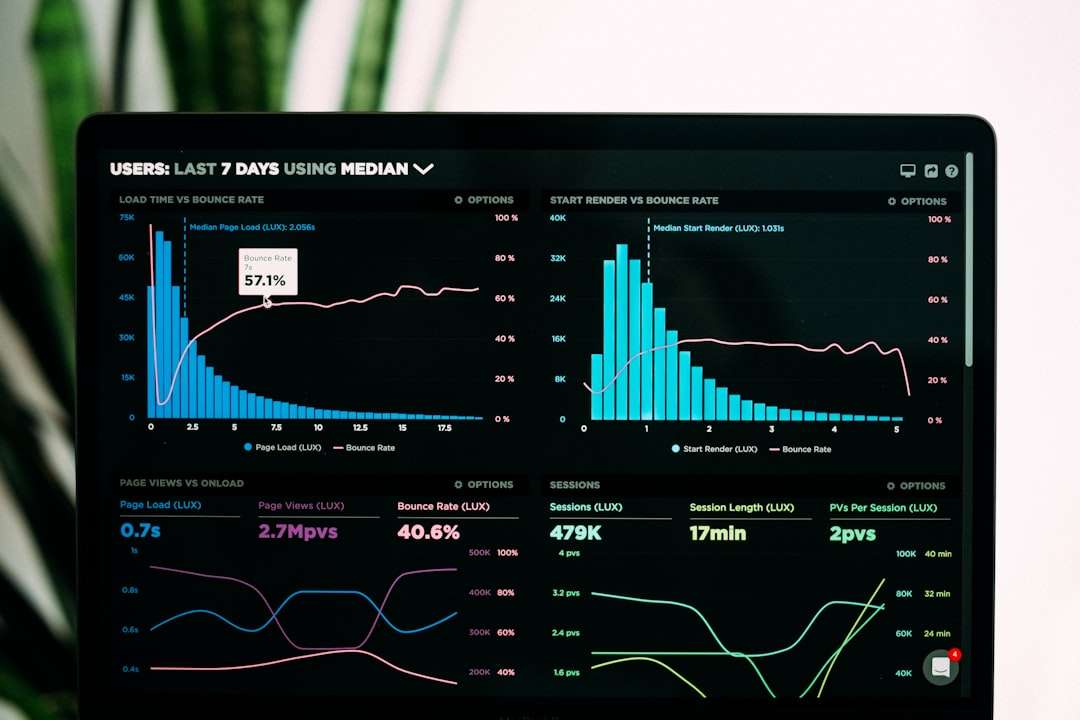
Analytics matter as well. If 8% of all requests receive 429 during normal business hours, the limits may be too strict, the clients may be too aggressive, or a feature may be making wasteful calls. If 429 jumps from 0.5% to 15% after a product release, the release should be reviewed fast.
Best Practices for Teams
- Publish clear limits. Developers should know the quotas before production traffic starts.
- Return Retry-After whenever possible. Guessing causes bad retry behavior.
- Use separate limits for reads and writes. A search request is not the same as a payment capture.
- Monitor 429 rates by account and endpoint. One endpoint may be the real problem.
- Offer higher limits through review. Some customers have valid high-volume use cases.
- Protect login and payment routes carefully. These paths affect trust fast.
The goal is not to punish clients. The goal is steady service. A good 429 system tells clients to slow down, gives them a safe retry time, and keeps the API healthy for everyone.
FAQ
What does HTTP 429 mean?
HTTP 429 Too Many Requests means the client has sent more requests than the API allows within a certain time period.
Is Retry-After required with 429?
No, but it is strongly recommended. Without it, clients must guess when to retry, which can increase traffic problems.
Should clients always retry after a 429?
Not always. They should retry only when the action is safe, the retry limit has not been reached, and the server guidance allows it.
What is the best retry strategy?
The best common strategy is exponential backoff with jitter, while respecting the Retry-After header when it is present.
Is 429 the same as 503?
No. 429 means the client hit a rate limit. 503 usually means the service is unavailable or overloaded at a broader level.
How can API teams reduce 429 errors?
They can improve caching, tune quotas, split limits by endpoint, add queues, review client behavior, and provide clearer rate limit headers.